Hear every user,
in their own words
An AI-powered user research platform. AI designs the study, runs live interviews, and writes the insight report—then connects with your behavior data to close the validation loop.
Our customers

Three steps to hear from your users
Work through your research question with AI
Describe your research goal in one sentence. The research assistant asks a few clarifying questions, then drafts an interview guide ready to publish.
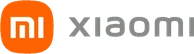
AI runs hundreds of interviews at once
Invite participants with a share link, an imported list, or inside your app. They answer by text or voice.
Get your report within hours
Findings, percentages, and supporting quotes are organized into an insight report. Export once a researcher signs off.
Start from what you know. Validate with results.
Every study starts from existing evidence and is checked against business results
 Research loop
Check existing evidence
heari checks your knowledge base first. If the evidence is already there, you get a sourced answer without new interviews.
Design and rehearse
Draft your interview guide and rehearse with simulated participants. Check question order, length, and leading wording before publishing.
Interview and observe
AI runs hundreds of interviews at once. Researchers can listen in or take over, and participants confirm a summary.
Researcher sign-off
Each finding comes with quotes and counterexamples, and a researcher reviews it before it goes into the insight report.
Validate with business results
ThinkingAI Agentic Engine checks findings against behavior data: confirmed, unproven or overturned.
Interview users worldwide, in their own language
Every participant in their own language. Every market in one report
Participants answer in their own language
Dozens of languages, by text or voice. The AI follows up in the same language.
Every market in one report
Answers in every language come together in one report. Quotes keep the original wording, with a translation in your team's language.
Compare findings by market
Break results down by country or language to see how answers to the same question differ across markets.
Hear tone and emotion
Voice answers are analyzed for tone and emotion, flagging hesitation, pauses and clear frustration. Researchers can replay the original audio.
The AI follows up on every answer, automatically
A survey stops at a score. heari keeps asking until it finds the real reason
How satisfied were you with your loan application?
You get a score, but not the reason.
The proof-of-income step is the main reason applicants drop out midway
47% · 044Every finding is backed by participants' own words
No quote, no finding. Click any citation to read the participant's exact words
Follow-up questions have rules
Follow-ups go to a set depth (which time, what happened, why) and stop when a participant can't or won't say.
Every interview gets a quality score
Low-effort and off-topic answers are flagged; a researcher decides whether flagged interviews count.
Findings come with quotes and counterexamples
Each finding shows how many participants back it, the quotes it cites, and what contradicts it.
Researchers have the final say
AI synthesizes, researchers approve. Only approved findings reach the report.
Families with kids care most about back-seat space
Once the car seat's in, there's basically no room for anyone else back there.
We take the grandparents out a lot on weekends, and three across the back is way too tight.
The salesperson never had us sit in the back on the test drive. It only hit us once we got home.
Interview users at the moment that matters
Reach users right after they churn or skip a purchase, while they still remember why
Set triggers based on behavior
For example, no login for 7 days, a refund request, or viewing a bundle without buying. When the condition is met, the invitation goes out automatically.
Ask while memories are fresh
Interview soon after it happens and you hear about that specific experience, not a vague memory weeks later.
Never pester users
Set frequency caps and quiet hours. Each user is invited at most once every 30 days and can opt out at any time.
Always-on interviews
Triggers stay on, so new interviews keep flowing into the same study and you can see changes as they happen.
Let your AI agents run user interviews too
Codex, Claude Code, or your own agent can call heari to run interviews and fetch findings
- MCP server and command-line tool (CLI)
- Structured output
- Human in the loop
- Same permissions and quota
AI proposes and executes. People decide.
AI runs and synthesizes the interviews. Your team confirms every finding
What AI does
- Drafts the interview guide from your research goal
- Moderates interviews and follows up in real time
- Synthesizes themes and surfaces key findings
- Finds the quotes and counterexamples behind each finding
What your team does
- Approves and publishes the interview guide
- Excludes interviews that don't meet the bar
- Reviews each finding: accept, edit, or reject
- Publishes the report and decides what to do next
Enterprise-grade data security
Built on ThinkingAI's work with 1,500+ enterprises. Your data stays yours, deployed your way.
Private deployment
Deploy in your own cloud or data center, so interview data never leaves your network.
Choose your data region
Choose where data is stored based on where you operate, to meet cross-border data requirements.
Access control and audit logs
Single sign-on, permissions by project, and a full audit trail of interviews, reviews and exports.
Data used only for your research
Interview content belongs to you and is never used to train models. Reports cite quotes by participant number only.
Start a pilot study with your own business question
Tell us the business question you most want answered, and we'll run a pilot study with you in heari.